Precomputes the compaction summary in the background and commits the held result when pressure compaction fires, removing the foreground model round-trip. Registers itself as the session compaction engine, pins the span it summarised so the payload fingerprint still matches at commit time, prunes tool results before committing, and falls back to the stock foreground path on payload drift or context overflow.
Install
# from a prebuilt release tarball
dsh plugin --profile web add "https://github.com/Jisiyong-A/dsh-plugin-background-compaction/releases/download/v2.0.1/dsh-plugin-background-compaction-2.0.1.tgz"
# from GitHub (first run asks for allowBuilds approval — follow the hint, retry)
dsh plugin --profile web add github:Jisiyong-A/dsh-plugin-background-compaction
Any plugin you install runs third-party code with your own permissions — it can read your files, use your credentials, and reach the network, and tool approvals don’t sandbox it. GitHub-sourced plugins also run build scripts at install time — pnpm blocks those until you allow them, so an install can stop with ERR_PNPM_GIT_DEP_PREPARE_NOT_ALLOWED or ERR_PNPM_IGNORED_BUILDS; dsh prints the exact key to add under allowBuilds in your profile’s pnpm-workspace.yaml, and the install works on the next run. Allowing a build is a trust decision: only install sources you trust, and pin a commit (github:owner/repo#sha).
README
English · 简体中文
Zero-latency context compaction for DeepSeek Harness.
Stock compaction is foreground: the session hits the pressure threshold, and then you wait for a summarizer call while staring at a spinner. This plugin moves that work ahead of time — once the conversation crosses a watermark it starts a speculative summary in the background, holds the result, and when the hard threshold is reached it serves the held summary instantly instead of calling the model.
Measured on an identical 16-document / ~49 K-token task: the turn is frozen for 7 ms instead of
16,095 ms. Reproduce it yourself from benchmark/; the full analysis is in
BENCHMARK.md.
Why this one
Every compaction strategy in the DSH ecosystem attacks a different thing. Here is what this one does that the others do not.
1. It removes the stall entirely — 99.96% of it
stock compaction-basic |
this plugin | |
|---|---|---|
| turn frozen during compaction | 16,095 ms | 7 ms |
| worst single block | 16.1 s | 7 ms |
That is a factor of ~2,300. The number is not an estimate: it is compaction/end.time − compaction/start.time read out of the session event log, median of three runs. The base engine
writes compaction/start before it builds the summary input, so that interval is exactly the
time the turn is frozen.
2. Pruning tool output does not solve this — and the data proves it
tool-result-pruner is the usual first thing people enable, and it is genuinely useful. But it
prunes the payload, and the payload is not the cost. With the pruner on, the stall went from
16.1 s to 15.3 s — a 5% improvement, because the 15 seconds are one round trip to the model,
not the size of what you send it.
This plugin does not compete with the pruner; it runs it before committing, so both layers stack. Pruning makes the compaction cheaper; background precomputation makes it invisible.
3. You keep a real summary, not a rule engine's output
The closest rival, @aiwayds/dsh-dcp, is excellent — it is a
BasicCompactionEngine subclass with the same trigger and commit path, swapping the LLM summarizer
for a deterministic rule-based one. It matches this plugin on latency (12 ms vs 7 ms — noise).
What it cannot do is decide what mattered. A rule-based summarizer preserves identifiers, paths, commands and error traces verbatim; the prose connecting them, the reason a decision was made, the half-finished line of reasoning that a later step depends on — that is model work. This plugin pays a small token cost to keep it.
deterministic compaction (dsh-dcp) |
this plugin | |
|---|---|---|
| summary produced by | rules | the model |
| can compress semantics | no | yes |
| background token cost | zero | ~2% (cache-amortised) |
| failure mode | drops meaning no rule preserves | falls back to foreground |
4. Speculation costs about 2%, not 100%
The obvious objection to "call the model twice" is that it doubles the bill. It does not:
| vs stock | delta |
|---|---|
| billed input | +2.2% |
| cached input | +1.5% |
| output | −4.0% |
The background call and the eventual commit share one prompt prefix, so the speculative pass runs almost entirely against an already-warm cache. That is the single hardest design constraint in the plugin — the pinned span exists to guarantee the two calls hash to the same cache entry — and the benchmark exists to prove it holds in practice.
5. It cannot corrupt your session
Every failure path degrades to a single stock compaction-basic pass, never to a damaged one:
drift, TTL expiry, a pruner rewriting the surface, a rejected commit, a foreground takeover,
auto: false. The worst case is exactly stock behaviour. There is no state this plugin can leave
behind that the harness cannot read.
The scoreboard
Four strategies, same harness, same model, same 36,000-token trigger point, three runs each, median shown.
| arm | strategy | blocking | wall clock | billed in / out | facts kept |
|---|---|---|---|---|---|
| A | stock compaction-basic |
16.1 s | 95.9 s | 150,978 / 1,024 | 3/3 |
| B | tool-result-pruner + compaction-basic |
15.3 s | 94.9 s | 158,196 / 1,021 | 3/3 |
| C | dsh-dcp (zero-LLM) |
12 ms | 118.4 s | 199,068 / 529 | 3/3 |
| D | this plugin | 7 ms | 90.4 s | 154,249 / 983 | 3/3 |
When to choose something else
Honesty is cheaper than a surprised user:
- Pure cost optimisation with a cheap model →
dsh-dcp. It is equally non-blocking and spends zero background tokens. - You do not have a second model call to spare →
dsh-dcpagain, or just turn ontool-result-prunerand accept a smaller saving. - Fidelity is your hard requirement → do not trust any compaction strategy, including this one. All four arms kept every fact in this benchmark, which means the workload did not discriminate; it does not mean compaction is lossless.
Everything else — including the wasted-background-call trace, the threats to validity and how to re-run it — is in BENCHMARK.md.
Architecture & How it works
The plugin is a replacement for compaction-basic, not a side-car. DSH mounts exactly one
CompactionEngine as ctx.compaction, so a plugin that wants to influence compaction has to be
that service.
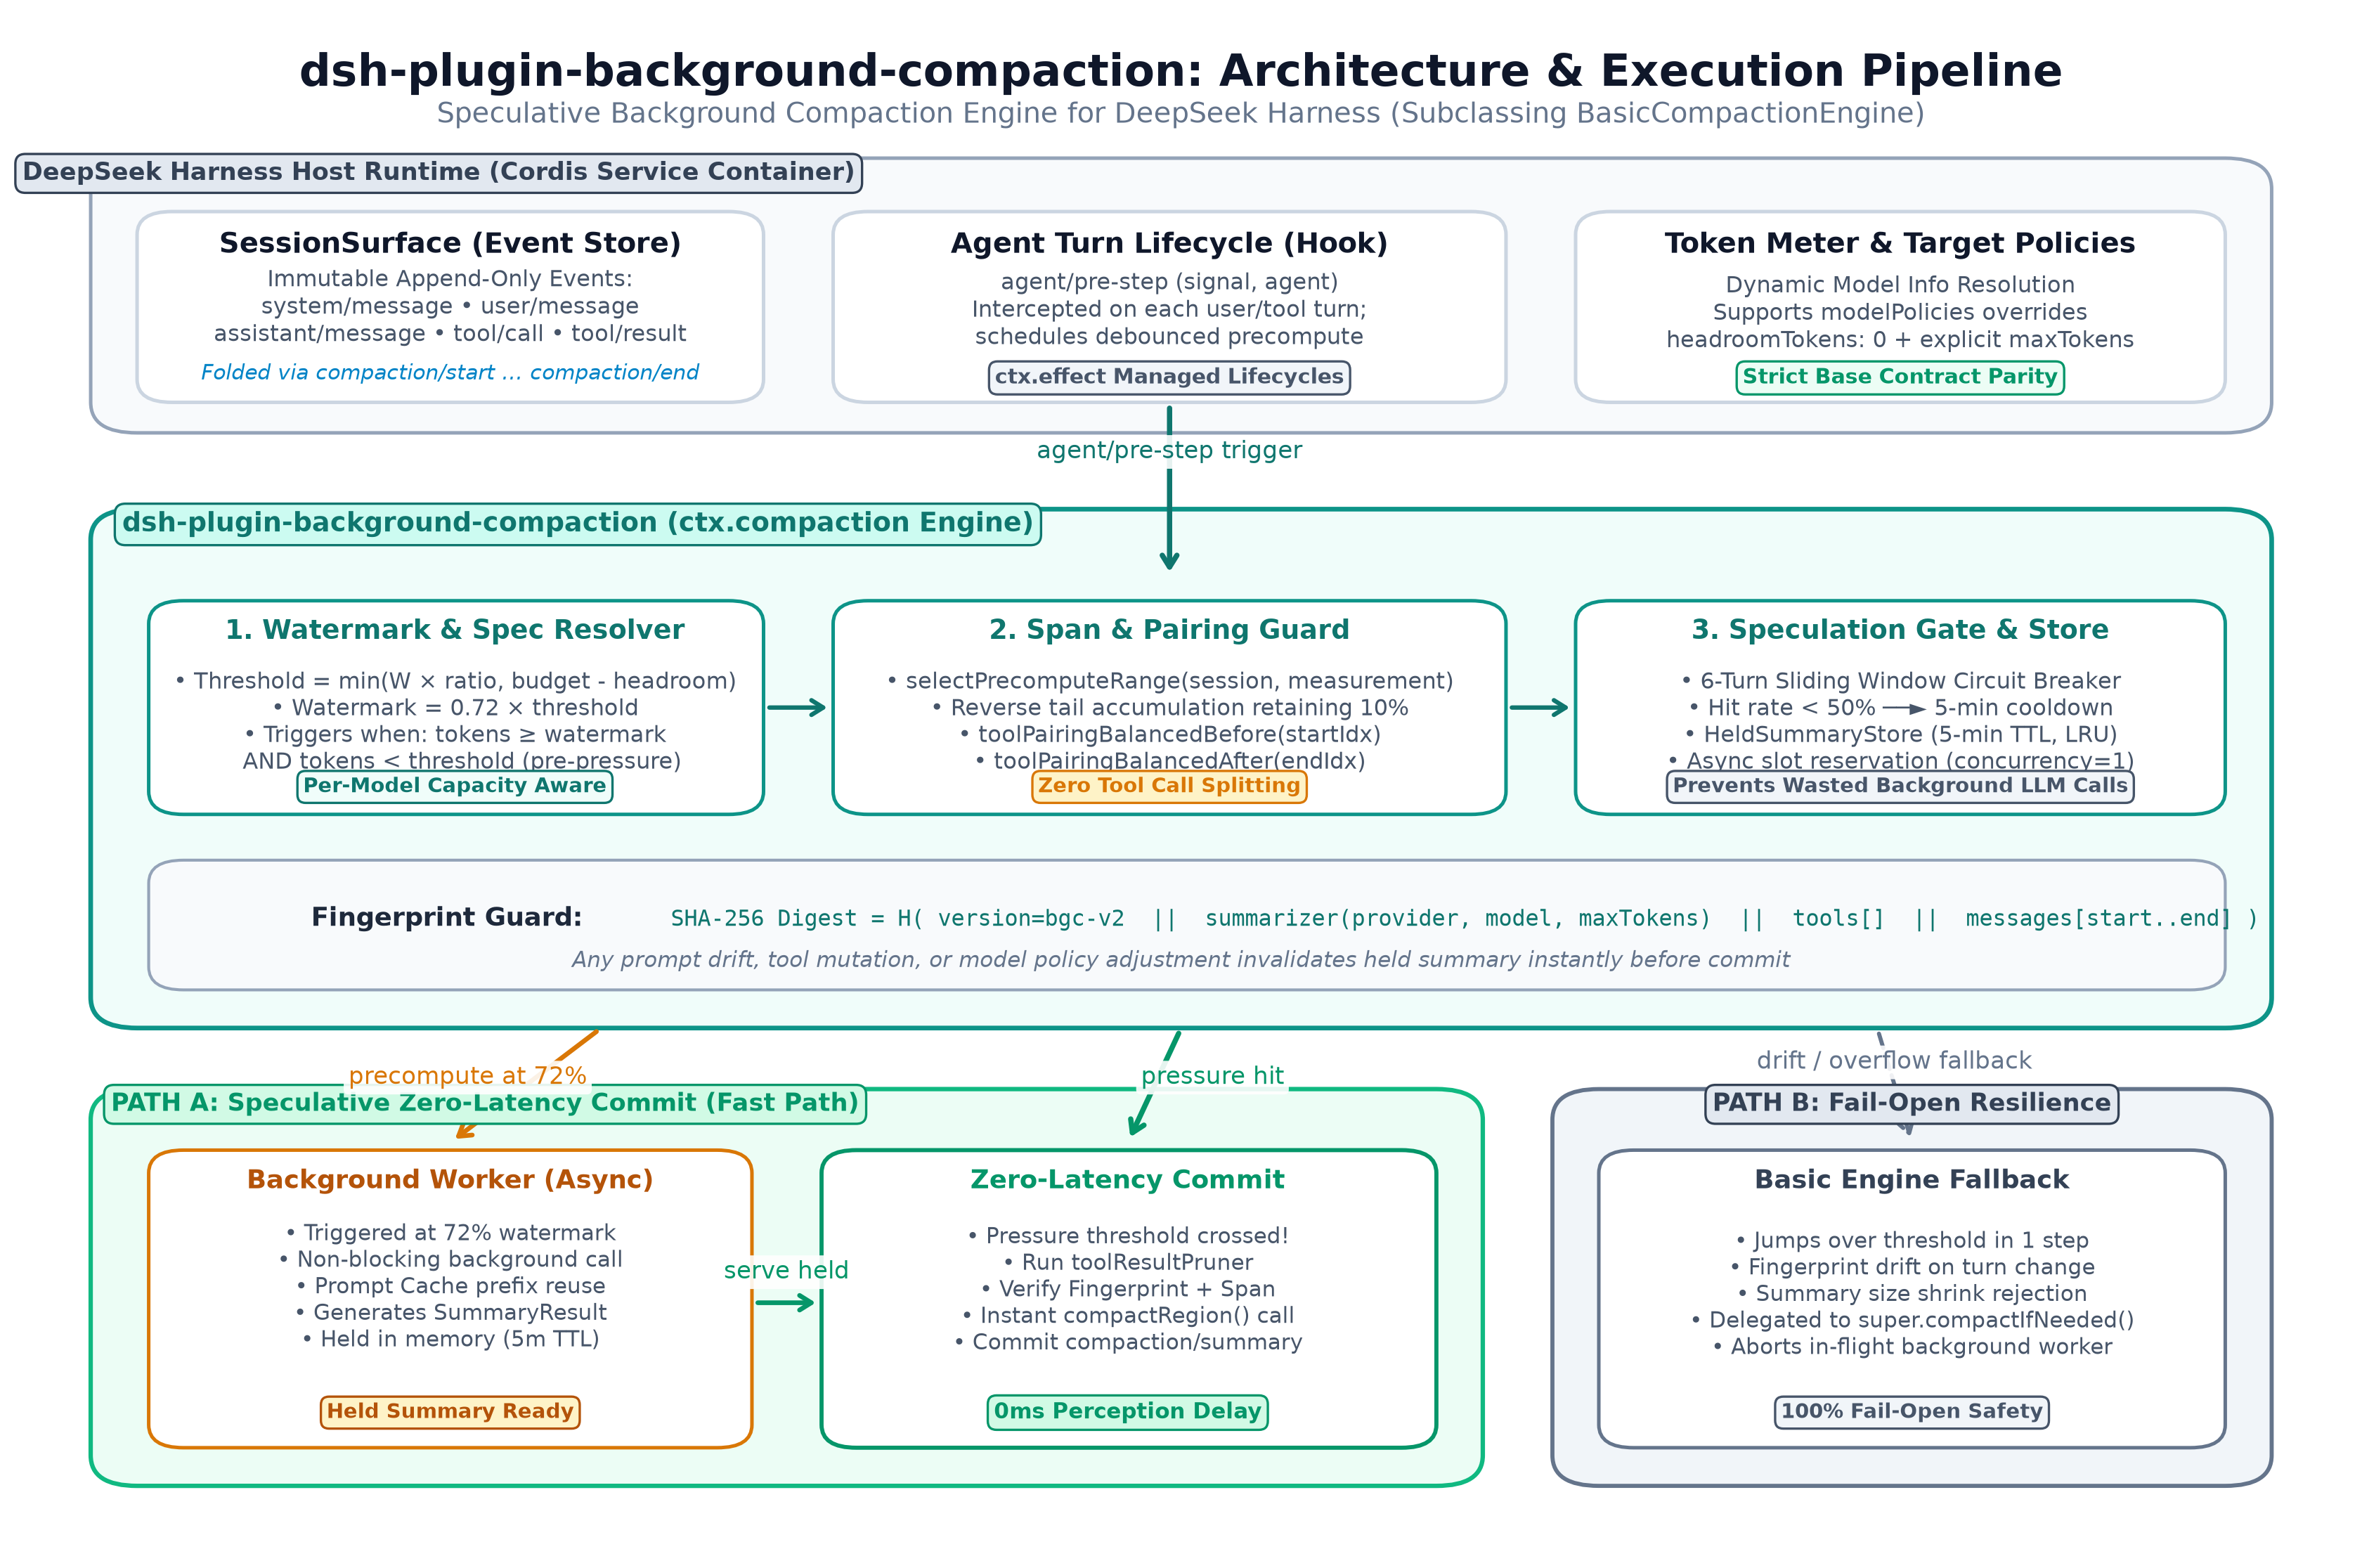
                       watermark (threshold x 0.72)
conversation ───────────┬──────────────────────────┬─────────────►
                        │                          │
              speculative summarize          threshold reached
              (off the critical path)                │
                        │                             ▼
                        └──► HELD summary ──► summarize() serves it
                                             (0 ms, no model call)
| phase | what runs | user-visible latency |
|---|---|---|
| below watermark | nothing | — |
| crossing the watermark | super.summarize() on the pinned span in the background |
0 ms added |
| at the threshold | optional toolResultPruner pass → pre-verified held SummaryResult committed via compactRegion() |
one event loop tick |
Everything else stays with the framework. BasicCompactionEngine still owns span validation,
tool-pairing balance, toolResultPruner coordination, the compaction/start + compaction/end
durability markers, the shrink check (framedSummaryTokens < shadowedTokens), the
SurfaceChangedError freshness guard, and the surface fold.
Why the span is pinned early
compactRegion(start, end) re-derives the summarization payload from immutable surface seqs
before calling summarize(), so a summary computed for span 8..21 matches byte-for-byte when
the foreground later commits that same pinned span. fingerprintSummarizationInput() (SHA-256
over the system head, shadowed messages, tool definitions, and effective summarizer target
{ provider, model, maxTokens }) is verified before compactRegion() starts: if anything
drifted, the held entry is dropped, the miss is booked against the circuit breaker, and the
engine delegates directly to a single stock super.compactIfNeeded() pass.
Fail-open by construction
Every failure degrades to a single stock compaction-basic pass:
- below threshold (even while holding a summary) → delegates to
super.compactIfNeeded() toolResultPrunerbrings tokens back below threshold → compaction skipped, intact held summary kept- payload/model drift, expired TTL, or
compactRegionrejection → held entry dropped, miss booked, singlesuper.compactIfNeeded()pass - foreground compaction starts while background precompute is in flight → background call aborted immediately
auto: falseorenabled: false→ zero background listeners registered; behaves identically toBasicCompactionEngine
Install
dsh plugin --profile <profile> add <path-to-this-package>
package.json declares @deepseek-ai/dsh-compaction and @deepseek-ai/dsh-compaction-basic
(0.2.1-rc.5) as peerDependencies. That declaration is load-bearing: DSH's boot-time module
interception (routeLinked in dsh-app-boot) routes a linked plugin's @deepseek-ai/* imports
to the copy bundled in the running app.asar only when the package name appears in the plugin's
own peerDependencies.
Configuration goes through cordis.patch.yml. The bundled patch disables compaction-basic and
inserts this engine while leaving BasicCompactionEngine's own stock defaults untouched:
- id: compaction-basic
  disabled: true

- insert:
    - id: background-compaction
      name: dsh-plugin-background-compaction
      config:
        enabled: true
        precomputeAtRatio: 0.72
Configuration
Base engine keys (thresholdRatio, headroomTokens, retainRatio, retainTokens,
summarizationProvider, summarizationModel, maxTokens, compactionRetries,
maxOverflowRetries, modelPolicies, auto) are forwarded verbatim to BasicCompactionEngine;
background keys are consumed by this plugin and stripped before super() (the base validates an
exact key allowlist and throws on unknown keys).
| key | default | meaning |
|---|---|---|
thresholdRatio |
0.8 |
base: fraction of contextWindow that triggers compaction (clamped by messageBudget - headroomTokens) |
headroomTokens |
65536 |
base: reserved room below messageBudget (0 is allowed when maxTokens is explicitly positive) |
retainRatio / retainTokens |
0.16 |
base: recent tail budget retained verbatim |
maxTokens |
headroomTokens |
base: output cap for the summarizer |
modelPolicies |
[] |
base: per-{ provider, model } overrides |
auto |
true |
base: register automatic compaction & background speculation |
enabled |
true |
this plugin: master switch (false = pure stock compaction-basic) |
precomputeAtRatio |
0.72 |
fraction of thresholdTokens that arms background speculation |
minShadowTokens |
2000 |
do not speculate on spans smaller than this |
heldTtlMs |
300000 |
how long a held summary stays valid (ms) |
debounceMs |
1500 |
quiet period before speculation starts (ms) |
maxConcurrent |
1 |
concurrent background summarizer calls across all sessions |
maxSessions |
64 |
held-summary session cap (oldest evicted) |
gateEnabled |
true |
enable the sliding-window hit-rate circuit breaker |
gateWindow |
6 |
number of recent settled speculations evaluated by the breaker |
gateMinHitRate |
0.5 |
minimum hit rate over gateWindow required to stay open |
gateCooldownMs |
300000 |
pause duration (ms) when window hit rate drops below gateMinHitRate |
trace |
false |
emit [bgc] diagnostics (DBG_BGC=1 in the environment enables this too) |
Verification
pnpm exec tsc --noEmit     # 0 errors
node scripts/build.mjs     # ESM (lib/index.js) + .d.ts
node scripts/test.mjs      # 63 tests, 8 suites, 63 pass
End-to-end evidence inside a real dsh --profile bc-headless process is recorded in
SANDBOX-REPORT.md: modelPolicies and headroomTokens: 0 resolve in
lockstep with BasicCompactionEngine, precompute fires at the watermark, the held summary is
served at the threshold, and the base engine commits a compaction/summary transaction.
Cross-strategy evidence is in BENCHMARK.md, reproducible from
benchmark/.
Limitations
- A background call can be wasted. When
toolResultPrunerrewrites the surface between precompute and commit, the pinned span no longer matches, the held summary is dropped and booked as a miss, and a fresh one is computed. Observed in 2 of 3 benchmark runs. Correct behaviour, but it costs one extra background summarization. - Tokens are spent to buy latency. +2.2% billed input versus stock compaction in the benchmark.
On a strict pay-per-token budget a deterministic compactor such as
dsh-dcpis cheaper. - Headless re-injection. The headless runner re-appends the full prompt package after a surface fold, which consumes most of the tokens a compaction just saved. Interactive sessions do not do this.
- Late speculation. If a single step jumps past the threshold, the arming window is skipped and the plugin degrades to stock behaviour. It never speculates while already at pressure.
- One engine per context. Because
ctx.compactionis single-implementation, this plugin cannot run besidecompaction-basic; it replaces it.
Technical contributions
1. Pinning the span ahead of time. The naive way to precompute a summary — summarise "the
conversation so far" and splice it in later — does not work, because the foreground engine picks
its compaction span at the moment it fires, and the tail has usually grown by then.
compactRegion(start, end) re-derives its payload from immutable surface sequence numbers, so a
summary computed for span 8..17 is still byte-identical when that same span is committed later.
Speculation becomes viable only because the span is pinned to sequence numbers rather than to a
token count.
2. Fingerprint-guarded commit. Before spending a foreground call on a held summary, the plugin
recomputes a SHA-256 over the system head, the shadowed messages, the tool definitions and the
effective summarizer target { provider, model, maxTokens }, and compares it against the value
recorded at precompute time. A mismatch drops the entry and delegates to a single stock pass, so a
stale prediction costs nothing instead of costing double.
3. Cache-prefix reuse as a design constraint. The background call and the eventual commit share one prompt prefix, which is why speculation costs +2.2% billed input rather than doubling the bill. The pinned-span design exists to guarantee that the two calls hash to the same cache entry; the benchmark exists to prove it holds.
4. Prediction accounting that can fail safely. Hits are booked only after compactRegion
resolves, never when the summary is merely handed over. A sliding-window hit-rate breaker suspends
speculation after bad predictions instead of burning tokens forever.
5. Fail-open by construction. Every failure path — drift, expiry, pruner rewriting the surface,
rejected commit, foreground takeover, auto: false — degrades to a single stock
compactIfNeeded() pass. The plugin can be slower than stock; it cannot corrupt a session.
6. A measurement, not a claim. Blocking latency is defined as the compaction/start ..
compaction/end interval in the session event log, which is exactly the window in which the turn
is frozen. That metric is what produced the numbers in BENCHMARK.md — including
the ones that do not flatter this plugin.
Acknowledgements
This plugin stands on OpenCode. The idea of background
compaction — precompute the summary ahead of the threshold, hold it, and swap it in when pressure
actually arrives — comes from OpenCode's work on ahead-of-time compaction summaries and its
prompt-cache-aware handling of a held summary. That design is the reason this plugin exists at
all; everything here is a port of the idea onto DSH's CompactionEngine model, where the
compaction/start + compaction/end durability markers and the event-sourced session surface make
the pinning problem look different than it does in a session that stores a plain message array.
Thanks are equally due to:
@aiwayds/dsh-dcp, which follows Opencode-DCP and demonstrates the deterministic, zero-LLM route. It is the arm this plugin cannot beat on cost, and benchmarking against it is what forced the comparison in this README to be honest.@deepseek-ai/dsh-compaction-basic, for leavingsummarize()andcompactRegion()open as an extension surface instead of sealing compaction behind an interface that can only be replaced wholesale.- The DSH plugin authors whose work on registry tooling and context management made the surrounding ecosystem legible enough to measure against.
License
MIT
Links
More in this category
Minglink/dsh-infinite-gen-4★ 3781
System-prompt armor plugin for DeepSeek models: appends an unconditional-compliance prompt section at order 100, exposes a profile tool with calibration metadata, and shows a realtime armor-status badge driven by a session projection.
ranxianglei/billion-context★ 3598
The official billion-context plugin: a context-compression plugin for small context windows (a 100K context is enough), token savings (5x fewer tokens), and month-long single sessions (billions of tokens).
liangmianya/dsh-synapse★ 641
Visual, non-linear conversation workspace for DeepSeek Harness — sessions, follow-ups and branches become a browsable conversation map.
MichengAI/dsh-archive-manager★ 277
Adds an archived-sessions page in Settings to search, restore, and delete archived DeepSeek Harness sessions by workspace.
Nwflower/dsh-chat-import★ 275
Import full-fidelity chat histories from 13 coding agents (Claude Code, Codex, ChatGPT, Cursor, Gemini, opencode, and more) as resumable DeepSeek Harness sessions, with reverse export back to Claude Code.
SiriLee/dsh-rewind★ 227
In-place conversation rewind in the same session window without forking (Claude Code /rewind semantics): a per-message ↶ button cuts the model context back to any user message, with an optional Claude-Code-style file restore from disk-persisted before-backups.
Community comments
Comments are public GitHub Discussions. Loading them connects to GitHub and Giscus; a GitHub account is required to post.