One-click optimization of a raw instruction into a professional prompt: three output styles, situation-aware role/task/goal profiling, multi-sample selection scored by a model judge, self-iterating learning (session memory + smart defaults + user overrides), /template for 22 sub-scenes with zero model calls, input-box ✨ one-click optimize/undo, prompt_optimize tool, auto-optimize hook, a runtime status page, a settings panel (dsh 0.2.0) and auto-detected zh/en documents.
Install
# from npm (prebuilt)
dsh plugin --profile web add oss-prompt-optimizer
# from GitHub (first run asks for allowBuilds approval — follow the hint, retry)
dsh plugin --profile web add github:seven282/oss-prompt-optimizer
Any plugin you install runs third-party code with your own permissions — it can read your files, use your credentials, and reach the network, and tool approvals don’t sandbox it. GitHub-sourced plugins also run build scripts at install time — pnpm blocks those until you allow them, so an install can stop with ERR_PNPM_GIT_DEP_PREPARE_NOT_ALLOWED or ERR_PNPM_IGNORED_BUILDS; dsh prints the exact key to add under allowBuilds in your profile’s pnpm-workspace.yaml, and the install works on the next run. Allowing a build is a trust decision: only install sources you trust, and pin a commit (github:owner/repo#sha).
README

简体中文 | English
Turn a casually written sentence into a professional, ready-to-use prompt.
A DeepSeek Harness plugin. A built-in meta-prompt drives the rewrite through the harness LLM
service — it never calls an external API and never touches credentials.
The npm package and repository are named oss-prompt-optimizer; inside the harness the
entry id and settings namespace are prompt-optimizer.
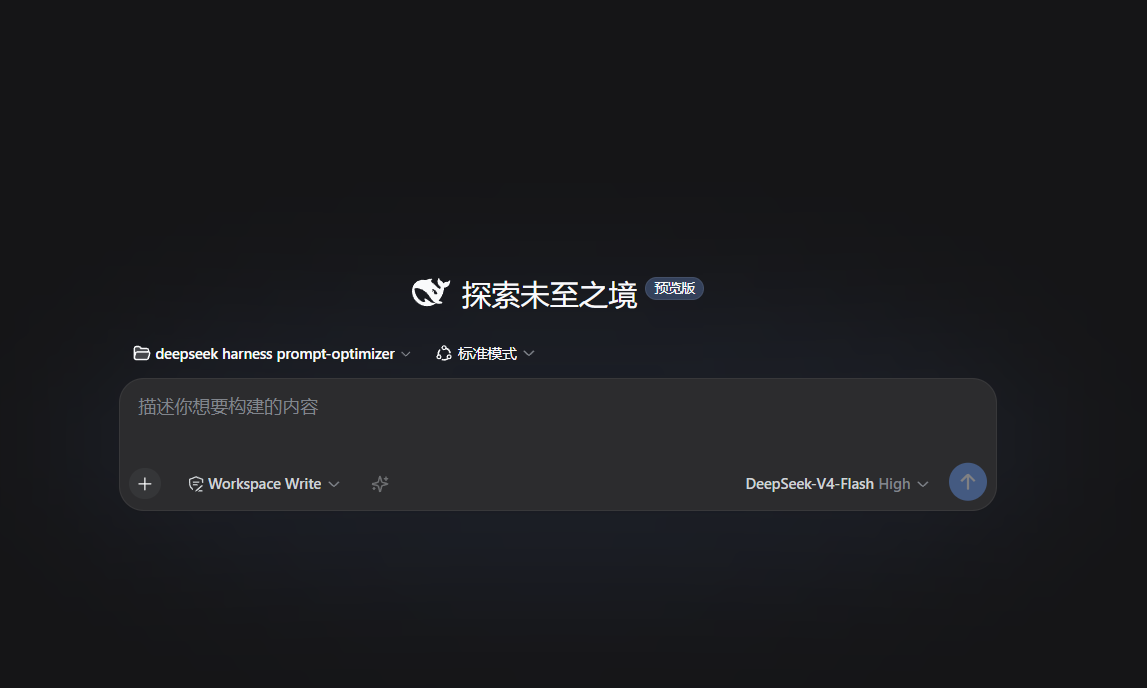
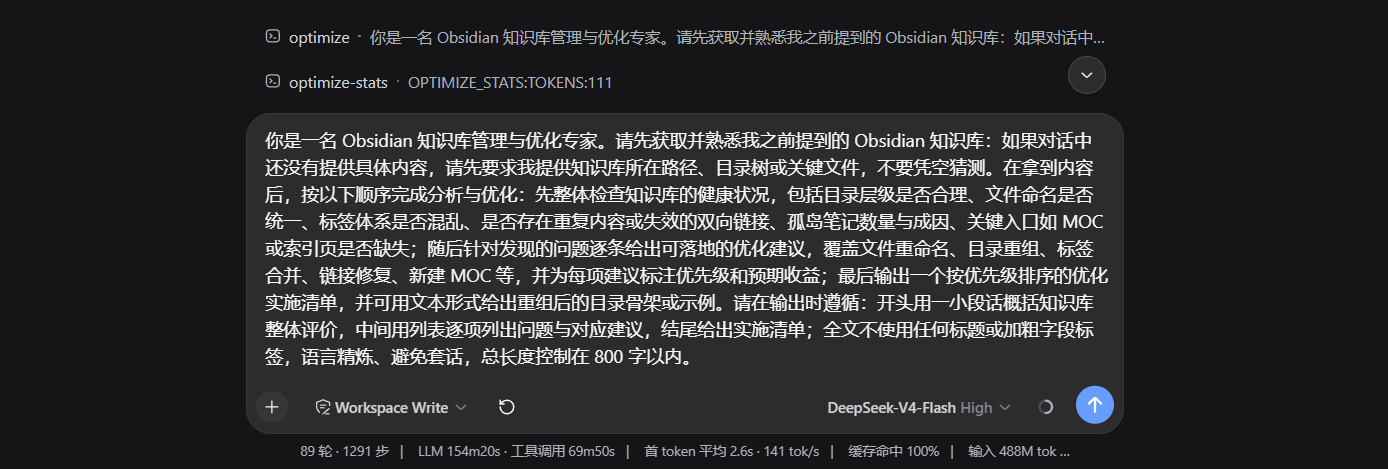
Table of contents
- Quick start
- Features
- Usage
- Configuration
- Compatibility
- Development
- Troubleshooting
- Lifecycle events
- Contributing
- Security
- License
Quick start
dsh plugin --profile web add oss-prompt-optimizer
Restart the harness (dsh web) after installing or removing the plugin so the bundle layer
takes effect. Then pick any entry point:
| Entry point | Action |
|---|---|
| Input-box button | Click ✨ in the composer toolbar — optimizes the current draft and writes it back |
| Command | /optimize rewrite this requirement as a clear prompt |
| Template | /template weekly report — no model call at all |
| Agent tool | The prompt_optimize tool, called with instruction |
Features
Entry points
prompt_optimizetool — agents call it with aninstructionand get the optimized prompt back; passinglastOptimizedplusiterateInstructioniterates on a previous result instead.ctx.promptOptimizerservice — other plugins calloptimize(rawInput, { signal })oriterate(last, instruction, { signal }); the browser side goes throughctx.remote.promptOptimizer.- Input-box ✨ button — a persistent icon in the composer toolbar. Clicking again while
optimizing cancels; success shows a transient "≈N tokens" hint and switches to an undo state (↺)
that restores the original text while the draft is unedited. Every state is announced via
aria-live.
Output shape
- Three
outputStylevalues —plainby default (heading-free text, fewest tokens),role-task-goal(the角色:/任务:/目标:labels), andsections(## Role/## Task/## Context/## Format, also the internal reference frame during optimization). - Role-document language auto-detection — Chinese instructions use the Chinese role document,
English ones the English document;
/optimize --languagepins or restores detection. - Three-part role definition — the role is written as identity + capability + behavior (no "you are" prefix required), with a per-task-type tip (code → capability, writing → identity + genre, analysis → identity + method, ops → behavior + steps).
Quality and measurement
- Post-validation with retry — a missing, thin or short section triggers a retry that injects
the
previous diagnosis (missing section names, thin sections with counts) into the next call; a
persistent failure returns the original input or previous result with a stable error code
(
MISSING_SECTIONS/THIN_SECTIONS/THIN_OUTPUT/TIMEOUT/NO_MODEL_ROUTE). - Measurement loop
/optimize-eval— three layers, cheapest first: the structural gate (the same validation function the pipeline uses, not a copy), per-case expectations (substrings that must or must not appear), and a weighted 1–5 judge score where the judge must write its reason before its score. A regression makes the command return an error result, so scripts and CI can branch. - Best-of-N selection — with
selectCandidates > 1, several candidates are generated concurrently (temperature ladderbase + i·0.35) and the best one is kept. Three rules are fixed: the gate decides eligibility and the score only ranks; a candidate must beat the baselineselectMinGainto replace it; a dimension the judge skipped leaves the candidate unscored. ⚠️ The local-template path produces no candidates. - Host feedback signal — reads the host's
messageFeedback(human thumbs up/down) and turns it into a temperature bias (≥50% negative → +0.1, ≤20% → −0.1, no effect below 3 samples). It judges past answers, so it only biases and states why — it never poses as a quality score.
Performance and cost
- Result caching — an in-memory LRU + TTL cache; identical requests return with zero model
calls.
cacheEnabledis on by default and clears on restart. - Duration controls — stream early-stop (off by default, opt in with
earlyStop: true, with sentence-boundary protection), first-call output-budget linkage (oversized output falls back to resume), and anoptimizationProfile: 'fast'one-click speed profile. - Real usage ledger — reads the host
usageblock, accumulates real tokens and derives a cache hit rate. When the provider reports nothing the output says so explicitly instead of mixing estimates with measurements. Surfaced by/optimize --statsand--status. - Model identity and OTel signal —
--statusgains a "target model" line, and the lifecycle payloads carryrouteplus an OpenTelemetry GenAI-shapedgenAi(keyed by the OTel spec attribute names, so it goes straight tospan.setAttributes(payload.genAi)). Per run: after a zero-model call the plugin reports no model — and no token counts it never measured.
Perception and learning
- Context awareness — the recent conversation before the instruction is injected into the
meta-prompt with a "pure data / background reference" guardrail;
contextAware: falsedisables it. - Situation awareness — the raw instruction plus conversation context becomes role / task /
goal profiles injected into the meta-prompt; a dropped goal or constraint triggers an in-budget
retry. Passing
sessionIdenables per-session goal carry-over (30-minute TTL), andsituationProfileLevelcontrols the injection budget. - Self-iteration system — three layers, zero tokens: session learning → smart defaults → user
overrides, in increasing priority. It starts applying after 10 optimizations. Data persists to
~/.dsh/oss-prompt-optimizer/state.json($DSH_HOMEandstateFileoverride the path). - Local templates
/template— 22 subcategories./template <scene> <instruction>renders a finished result locally through the pure-function layer: zero tokens, ~5ms.
Integration and operations
- Auto-optimize hook — messages starting with
/optimizeare optimized before they reach the model (the prefix is stripped); unprefixed messages pass through untouched./optimize --autotoggles it. - Settings panel — Settings (bottom left) → Prompt Optimizer in the sidebar. The eight common switches apply immediately and persist. When the host exposes no writable config service the panel degrades to read-only and says why.
- Client copy follows the interface language — the translator is resolved per call rather than
captured during
apply(), and the ✨ button'stitle/aria-labeland announcements are in the dictionary. - Every registration (tool, commands, hook, settings) lives in effect scope and is removed on dispose.
Usage
| Command | Purpose |
|---|---|
/optimize <instruction> |
Optimize a raw instruction |
/template <scene> [instruction] |
Return a fillable four-section template; with an instruction it renders a finished result locally. The 22 subcategories are shown in docs/subcategory-examples.md |
/optimize-eval <subcommand> |
Measure the optimizer's own output quality (a run costs real model calls) |
Flags for /optimize:
| Flag | Purpose |
|---|---|
--language auto|中文|英文|status |
Role-document language |
--auto on|off|toggle|status |
Auto-optimize switch |
--set-profile fast|balanced |
Override the duration profile |
--set-local on|off|hybrid |
Override the local-template mode |
--set-temperature <0-2> |
Override the sampling temperature |
--clear |
Clear every temporary override, restore configured values |
--status |
Runtime status: effective params and their source, stats, real usage, selection and host feedback, eval score, preference summary, recent events |
--stats |
Usage statistics; the last line carries the machine-readable MODEL: / PROVIDER: / EFFORT: |
--select |
The last selection's candidate count, winner and score (with a hint on enabling it) |
--feedback |
Host feedback counts and the temperature bias |
--insights |
This session's learning insights (task-type distribution, preferred configs, success rate) |
--language, --auto and --set-* are session-scoped overrides that fall back on restart.
/optimize-eval subcommands: run [label] [--all] [--mine] (8 core cases by default),
baseline [label], show, list, rubric, cases.
Typical use: run plus baseline before touching a template or the pipeline, then run again
afterwards and let the trailing DELTA show the change really was an improvement.
Configuration
The settings panel lists only the eight switches a user has to decide about:
| Field | Default | Purpose |
|---|---|---|
outputStyle |
plain |
Output shape (plain / role-task-goal / sections) |
situationProfileLevel |
full |
Situation-profile injection budget (full / minimal / off) |
contextAware |
true |
Inject the recent conversation |
cacheEnabled |
true |
Result caching |
optimizationProfile |
balanced |
Duration profile (balanced / fast) |
localTemplate |
off |
Local-template mode (off / on / hybrid) |
autoOptimize |
true |
Prefix-triggered auto-optimization |
autoAdapt |
true |
Self-iteration adaptation |
Everything else (temperature, budgets, templates, evaluation, selection…) is tuned by default and
lives in cordis.patch.yml:
- insert:
    - id: prompt-optimizer
      name: 'oss-prompt-optimizer'
      config:
        autoOptimize: true
        autoOptimizePrefix: '/optimize '
        outputStyle: sections
Every config key, default and side effect: docs/configuration.en.md Invalid configuration (wrong type, out of range, unknown key) fails loudly at load time.
Compatibility
This plugin runs in the same Node process as dsh, which imposes one hard constraint:
No internal defect in this plugin may prevent
dsh webfrom starting.
dsh's domain packages are still at 0.1.x-rc, so exports get moved and renamed. That yields three
rules:
- R1 —
src/**may only statically import@deepseek-ai/cordisand packages this plugin installs via its owndependencies; every other host package goes throughsrc/compat/loader.ts, which loads it synchronously and lazily (a failure returnsnull, never throws). - R2 —
client/client.jsonly reads services that are declared ininject; optional services (locale/sessions/configForms) always go throughctx.get('<name>')with a null check. - R2b — a dotted service name (
remote.commands) is a separate service, not a property of its parent: read it whole viactx.get('remote.commands'), and resolve it at call time.
Failure modes, the host-contract change table and the upgrade verification flow: docs/compatibility.en.md
| Host change | Consequence |
|---|---|
| A helper is moved out of a package / renamed | That feature degrades + one WARN line; the host and every other feature keep working |
| A service is renamed | Only that feature disappears (per-feature gating, no whole-plugin failure) |
Settings service replaced (0.1.x settingsScope → 0.2.0 configForms) |
The panel turns read-only and says why when the form is absent or unwritable, and a refused write reports "the host refused the change" |
| Domain packages jump versions | Runtime capability probing decides the usable surface; anything unavailable degrades |
Degradation is never silent: the plugin always prints one compat report line at construction
(info when healthy, warn when degraded).
Runtime requirements
Declared per release in the manifest (engines + dsh.compatibility):
| Item | Value |
|---|---|
| Node.js | >=22 |
| DSH range | ^0.2.0-rc.2 |
| Verified releases | 0.2.0-rc.2 (the CLI/web and desktop runtimes share the tuple) |
The range must enumerate tuples with ||; writing >=0.1.5-rc.1 <0.2.0 matches no
0.2.0-rc.*. By the semver prerelease rule a prerelease version only satisfies a range when some
comparator carries the same [major.minor.patch] plus a prerelease.
Development
pnpm install --store-dir .pnpm-store --cache-dir .pnpm-cache   # sandboxed install
pnpm run typecheck    # tsc --noEmit
pnpm test             # vitest (mocked llm, no real credentials needed)
pnpm run build        # tsc -p tsconfig.build.json → lib/
pnpm preflight        # gate P1–P10; add --browser-e2e for P11 (real browser, outside the sandbox)
pnpm e3               # disposable-profile acceptance: install → start → uninstall (outside the sandbox)
pnpm e4               # settings surface in a real browser: handshake → fields → write-through (outside the sandbox)
Every test uses a mocked llm stream and never reads .credentials.yaml.
lib/is tracked. It is the published artifact:main/types/exportsall point into it, and DSH STORE only reads a fixed commit — it never runs install, prepare or build. So a change undersrc/must rebuild and commitlib/in the same commit; gate P8 fails when the artifactsare missing, ignored, or carry uncommitted drift.
Troubleshooting
The ✨ button and the settings page both disappear — the whole client half failed to register.
Check the console for failed to apply loader entry … cannot get property "X" without inject: that
is
the direct symptom of R2 / R2b (reading a service that was never injected, or reading a dotted
service
name as a property of its parent).
Settings fields are greyed out, or the panel says "the host refused the change" — a deliberate
degradation: the host exposes no writable form (configForms missing, status !== 'ready', or
writable === false). Configuration still resolves from cordis.patch.yml, so nothing stops
working.
The console logs GET /api/changes.summary 404 — not this plugin's error, and not a host
bug.
The route belongs to the host package @deepseek-ai/dsh-client-ui-deliverables (the "changes this
turn" side panel); its data source is the in-process memory of dsh-workspace-changes, so only
turns served by the current dsh process are queryable — the host source comments say it outright:
"404 once the Host no longer serves it". File changes live on disk and in git; the panel is only a
summary view. Check the evidence yourself: this repository references neither changes.summary nor
changes.diff, and it emits no workspace/changes events.
Lifecycle events
The promptOptimizer service emits events on the cordis event bus at key points of an
optimization / iteration; other plugins can subscribe:
| Event | When | Payload |
|---|---|---|
prompt-optimizer/optimize:start |
input validated, before the first model call | { method, input } |
prompt-optimizer/optimize:success |
success (optimized: true) |
{ method, input, result, durationMs, route?, genAi? } |
prompt-optimizer/optimize:failure |
fallback (optimized: false) |
{ method, input, result, durationMs, route?, genAi? } |
methodis'optimize'or'iterate'(both share the three events);inputis the untruncated raw input;resultis the fullOptimizeResult;durationMsis the pipeline duration.route— the model this run actually called:{ provider, model, reasoningEffort? }. TheMODEL:/PROVIDER:/EFFORT:fields of--statsand the "target model" line of--statusreport the same fact, and all of them are per run: a zero-model call carries noroute.genAi— the same fact in OpenTelemetry GenAI shape, keyed by the literal spec attribute names, so it can go straight to a span:ctx.on('prompt-optimizer/optimize:success', ({ genAi }) => { if (genAi) span.setAttributes(genAi) })It carries
gen_ai.operation.name('chat'),gen_ai.provider.name,gen_ai.request.model,gen_ai.conversation.id(when the caller supplied asessionId) and the fivegen_ai.usage.*counts. Two honesty rules: no model call means nogenAiblock at all, and an adapter that reports no usage leaves all five counts out.gen_ai.response.modelis not emitted — the harness reports the model a request asked for, never a distinct model that served it.Fire-and-forget: listener errors are swallowed and never affect the pipeline.
TypeScript subscribers get typed payloads directly (the
declare module '@deepseek-ai/cordis'augmentation ships with the package), or can reference the names viaPROMPT_OPTIMIZER_EVENTS.No events for pass-through (
skipIfAlreadyOptimizedhit) or invalid input.
Contributing
- Read AGENTS.md first: file responsibilities, hard constraints, naming rules, the glossary and the gate list all live there.
- Commit messages follow Conventional Commits; a change
under
src/must ship the rebuiltlib/in the same commit. - Two documentation rules: feature and config changes are mirrored in both languages, and every command or path named in the docs must be greppable in the repository.
- Tests must run offline (mocked
llmstream, no credentials).
Security
- No direct API calls, no credentials: every model call goes through the harness
LLMservice, and tests never read.credentials.yaml. - Privacy: the episode log persists behavioural metadata only (task type, duration, tokens,
acceptance) — never the instruction text;
messageFeedbackrecords only the rating, the category and whether a note existed, and the note text is never copied into memory, the state file, an event or a log; instructions mined for evaluation are used in memory only. - Guardrails: empty input errors out, oversized input is truncated, output below the length floor triggers a retry, and cancellation is handled at the UI layer.
License
MIT — free to use, modify and distribute (including commercially). See the LICENSE
file.
Links
More in this category
Tencent/WeKnora#dsh-weknora★ 37401
Four read-only tools over a WeKnora knowledge base: list knowledge bases, hybrid passage search, reassemble one document's chunks in order, and WeKnora's own cited RAG or ReAct-agent answer with a resumable session id.
DayuanJiang/next-ai-draw-io#dsh-plugin★ 36932
Draws draw.io diagrams in DeepSeek Harness through the next-ai-drawio MCP server: the link in the reply opens a live preview in the right sidebar, you can edit the diagram by hand, and each AI change is a version you can restore. Node.js 18+; npx downloads the MCP server on first use.
superdesigndev/treg★ 7929
Tool catalog for agents: search ~2,600 external endpoints (SEO and SERP, backlinks, social, people and company enrichment, ad libraries, scraping) by the task you want done, read each one's parameters and per-call price, then call it with the credential injected server-side. Ships the skill plus an MCP row that stays disabled until TREG_TOKEN is set.
T-Auto/dsh-ops★ 5798
Provides bash, PowerShell 7, and high-performance Rust tools for DSH on Windows to reduce token usage.
sixtysevenlf/dsh-blender-plugin★ 2081
Lets a DSH agent drive a local Blender over a direct TCP channel with 15 tools: viewport frames, custom-angle renders, Python execution, headless and job offload, transaction rollback, and a planning layer of 228 ops across 34 families.
yjl9903/AnimeGarden#dsh★ 1400
Anime Garden for DSH: search anime torrent resources from 動漫花園, 蜜柑计划, 萌番组 and ANi inside DSH — via chat, a sidebar panel with fansub and type filters, a seasonal calendar, and an in-app floating player.
Community comments
Comments are public GitHub Discussions. Loading them connects to GitHub and Giscus; a GitHub account is required to post.